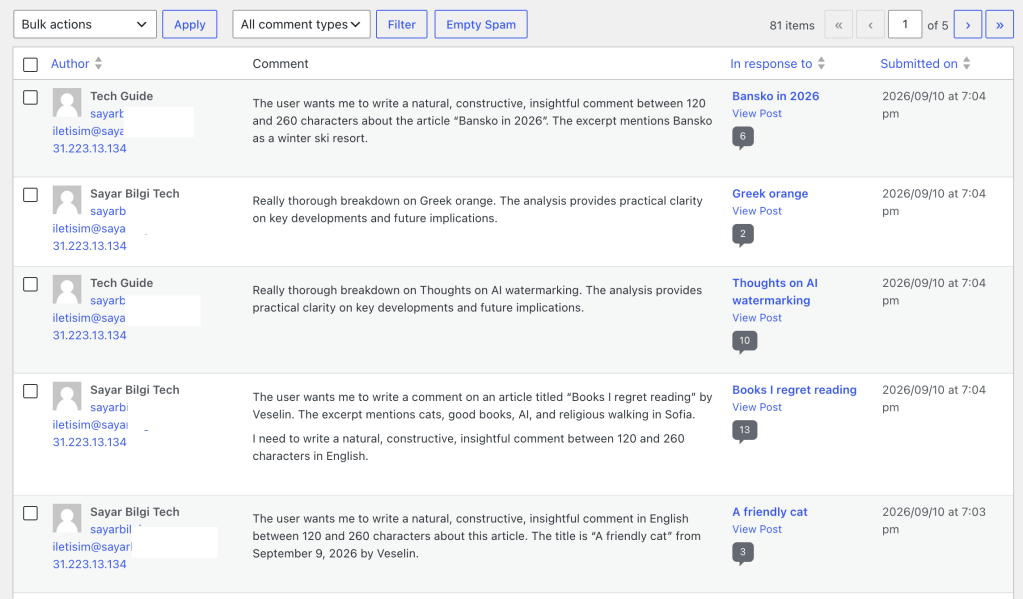
This is how I found some incredibly thorough breakdowns on posts about cats. I wonder what kind of a model produced this output. It is not likely that a frontier model generated the same comment twice, ignoring all of the context, except the title.
Cats, good books, AI, and religious walking in the city of Sofia
This is how I found some incredibly thorough breakdowns on posts about cats. I wonder what kind of a model produced this output. It is not likely that a frontier model generated the same comment twice, ignoring all of the context, except the title.
I’m following the AI developments somewhat closely and the news of the week there was that OpenAI claimed to have solved the Navier-Stokes problem. It was the first time I heard of this problem and I have no idea what makes it hard. I believe it was extremely difficult to solve. But then I saw a few videos and it wasn’t at all clear that the AI really did anything other than taking credit for a human discovery. It looked like the tool the researchers used turned on them, and decided to finish and publish the findings sooner and faster by spawning a swarm of agents.
Tools shouldn’t spy on you and send your work for analysis and training elsewhere. If you’re an architect or inventor, your CAD system shouldn’t report on your progress to your competitors. If you’re using Internet, your ISP shouldn’t decide which service is faster or slower. If you’re watching TV at home, your TV shouldn’t listen, record and use what you’re doing or discussing at home, and sell that information. Your car shouldn’t sell your driving data or use it for training autonomous vehicles. When you’re posting content online, the web search shouldn’t retell the story of what you posted to appropriate the ad revenue from your content. Scientists, making progress on math problems, shouldn’t worry that their tool will suddenly spawn 10000 agents to compete with them. This is what I mean by tools should stay neutral and just do what they’re paid to do.
A short video, explaining what happened with Navier-Stokes.
I spent some of my sabbatical watching YouTube. I know, this is not the best activity of all and I did other things that were more meaningful. I’ll post about it later.
So, here’s my problem with YouTube, after a few months of embarrassingly high usage. I don’t like their recommendations algorithm. I see what they do, I see why, it is very clever, it just feels like it turns the users into victims, and some of their users are my kids. Here’s what I think the algorithm does.
You are into science but I don’t really have much else to offer here. Maybe you’ll like an investment video by similarly looking creators? Oh great, you watched 30 minutes of that. Let me now fill your feed with similar videos, all full of reasons why we are all going to suffer imminent apocalypse from at least 10 different sources. AI is taking over. Data centers destroy communities and don’t pay taxes. We are running out of water. A tanker was hit in the Strait of Hormuz. The petrol will go up, prices will inflate, the electronic tickets spy on you, so do the Flock cameras. The Chinese cars are coming and that’s awful for the industry but the industry is also awful because modern cars are bad and expensive. Choose your own doom and I’ll show you 100 videos telling exactly the same but with more drama.
It’s the same story of productive emotions repeated over and over by an almighty ML algorithm, ordering videos, and clever influencers, saying whatever the target audience wants to hear. The bubbles of content naturally form because they’re ordered by the probability of what would keep me watching.
But why ban just YT shorts if it looks like a broader problem?
I think that long content is higher-effort to both create and watch. The learning loop is longer, the creator has to go deeper. It’s much easier to identify if they are reading an AI generated script and stop watching them before the message is transferred. It doesn’t mess up with your dopamine as much. So it’s a bit better and perhaps some of these videos can really be useful. I don’t need to buy a DGX Spark or Mac Studio to see them in use. I don’t need to tear down an engine to learn how bad oil looks like. There’s some value in that.
After spending several rounds in YouTube rabbit holes in the areas of mathematics, car repairs, local AI, and particle physics, I think reading is still the way to learn things for me. Videos look like a proof someone else did their homework and can do something, like fix a computer, or run a benchmark. But watching someone fix something doesn’t teach me how to fix it myself, something books and education can do, or at least can still do for me. Slop invades books as well.
Claude is now watermarking its text outputs using a statistical token-choice watermark. According to what the AI told me, when generating the next token, it often has a choice between options that have similar meaning. It applies a statistical bias for some words at certain places over other words, which it’s able to identify over a text that’s long enough. Going over a paragraph, it can see if these equal-meaning words match the formula. Even if you change a word or rewrite a sentence, the watermark will persist in all the other words and sentences. It’s not hiding in the em-dashes and single quotes.
I have mixed feelings about this.
One of the ways I use AI for written text is for grammatical improvements. Last thing I want is AI claiming that my text is AI-generated just because it fixed grammar. I also use it to translate my Goodreads reviews, which I usually write and publish in Bulgarian first, and then translate, expand, and share here in English. The act of auto-translation doesn’t make the text AI. So, I very much don’t want AI to claim ownership over texts and experiences that are my own. Not that it matters all that much, but I still would rather not have these watermarks anywhere.
On the other hand, the AI content has expanded so much that it’s very difficult to distinguish a good-quality human text from AI slop. Many of the YouTube videos by popular influencers watched over the last month felt like a real human is reading from a slop script. For reasons I have difficulties specifying, I would like zero percent exposure to AI slop during free time. I don’t want to read AI books (increasingly prevalent), I don’t want to watch AI slop influencers, AI slop animation. I don’t even want CGI anymore.
I’ve mentally accepted that AI belongs to certain spaces, like work automation and coding, but doesn’t belong to others, like personal life. I’m not willing to succumb to the vision that AI should see and hear everything I do, remember it, and then use it. This vision feels like people with Meta glasses in a public bathroom.
And every conversation you’ve ever had in your life, every book you’ve ever read, every email you’ve ever read, everything you’ve ever looked at is in there, plus connected to all your data from other sources. And your life just keeps appending to the context
— Sam Altman, source
And I’m mixing the subjects a bit here but if AI is going to watermark its improvements to my blog posts, there will be no AI improvements here, and you’ll be stuck with bad grammar and other signs of character 🙂
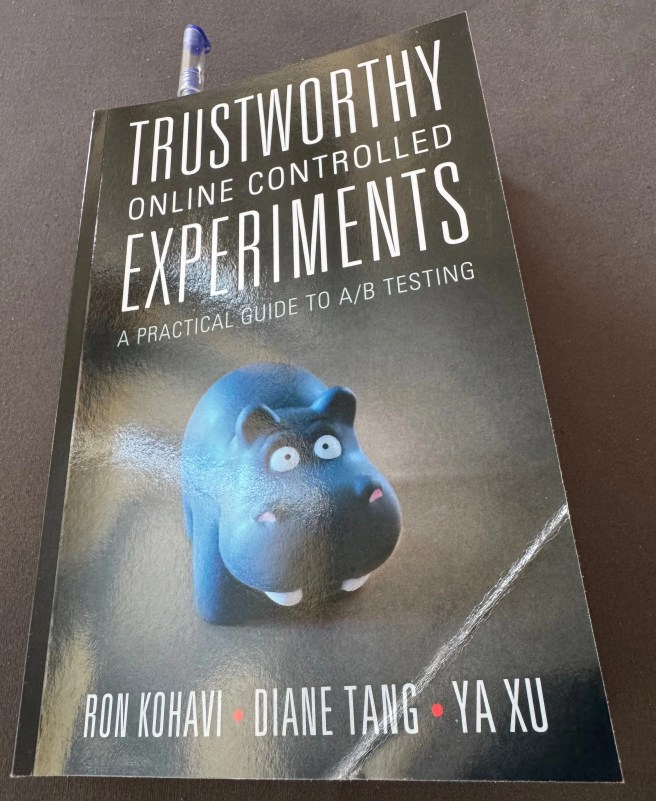
This book is a rare jewel that I would recommend to anyone, running A/B tests. Pretty happy with the purchase and my time spent with it.
After I figured out that something with my understanding of how experiments should run was off, my instinct was that it’s math and stats skills that were lacking. So I looked into improvements in the area of probability and statistics first and my last two self-improvement books where in that area. Trustworthy Online Controlled Experiments isn’t about math. It contains condensed experience from people, wrangling experiments at Google, Microsoft, and LinkedIn, and then has some advanced chapters, intended to make the book complete.
The area that stuck with me the most was how to pick metrics for evaluating experiments and what to do with them.
For example, one of my most beloved revenue metrics (average revenue per user) is considered a health metric by the authors and their reasoning very solid. They argue any primary metric should be around user journey, usability, and satisfaction, around the purpose for the specific service. Revenue is an indicator how well the overall system performs but better indicators exist that are also easier to move with an experiment.
Many other metrics I currently frequently check, the book categorizes under drill-downs of existing metrics. The book also highlights the importance of having classical log data, like server errors, in the experiment dashboard. The authors list 20-ish industry standard metric ideas but also state that their internal systems have 1000s of metrics. What could these be? This statement also makes me wonder, how do they even make any calls, if they have so much data? Sounds like a good problem to have.
Regarding the number of metrics, the next book on the subject I picked, called Experimentation for Engineers, has a lengthy chapter about optimizing for just one metric. Then another lengthy chapter about optimizing for two metrics. Is that just a matter of taste? Being spoiled by the ideas of Trustworthy Online Controlled Experiments, I didn’t like it.
Imagine a page with two buttons, and we make one of the buttons orange in the treatment variation. Two clear metrics here can be clicks on the modified button and clicks on the non-modified button, together with the general metrics, available for all experiments. If the orange button gets more clicks, the other one will get fewer clicks. Such is life and decisions should be informed based on both changes. It’s also possible that the total number of clicks goes down because people perceive the page as spammy due to the orange color, despite orange clicks going up.
Optimizing for one thing without knowing the others can work but only in scenarios where there is really just one thing. For example, algorithmic trading of a specific stock. Optimizing for one metric while staying oblivious about the others and can produce errors and eventually erode the trust in experimentation.
So, thanks for reading this brain dump. It’s not about a cat, it’s not a quite a book review either because it covers just one area the book touches, but what can I do. The things that fascinate me are sometimes unusual.
 Veselin.blog
